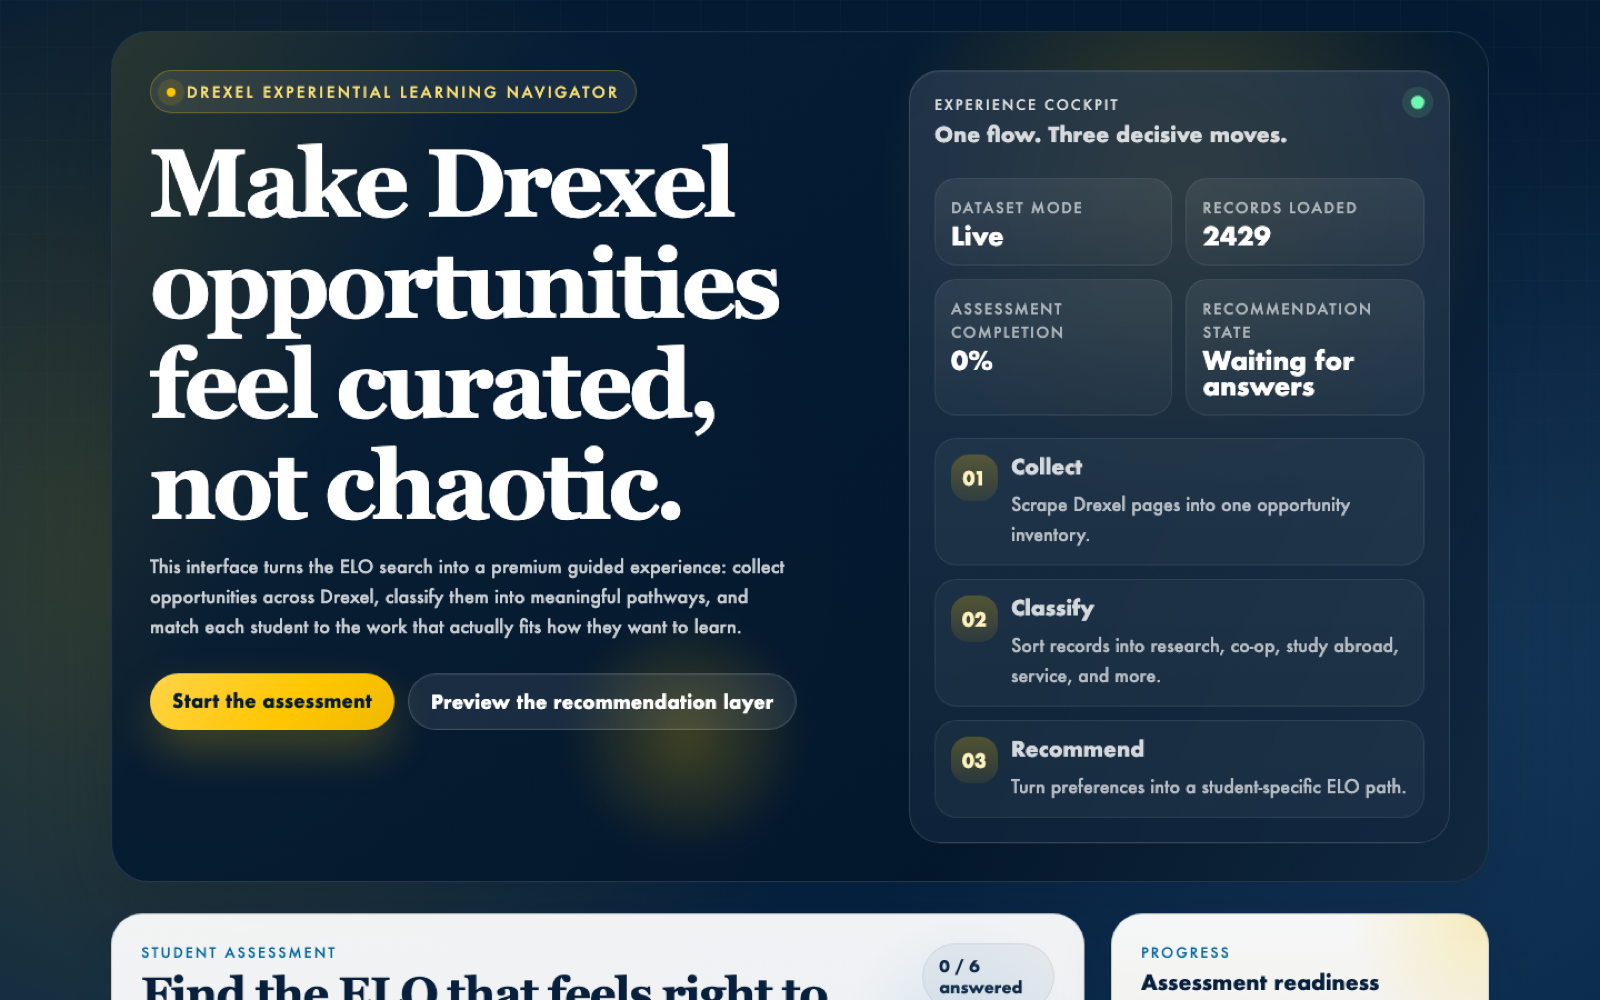
2,429 opportunities crawled and classified
Built for
Drexel students choosing between co-op, research, study abroad, and service
Project
Drexel ELO Recommender
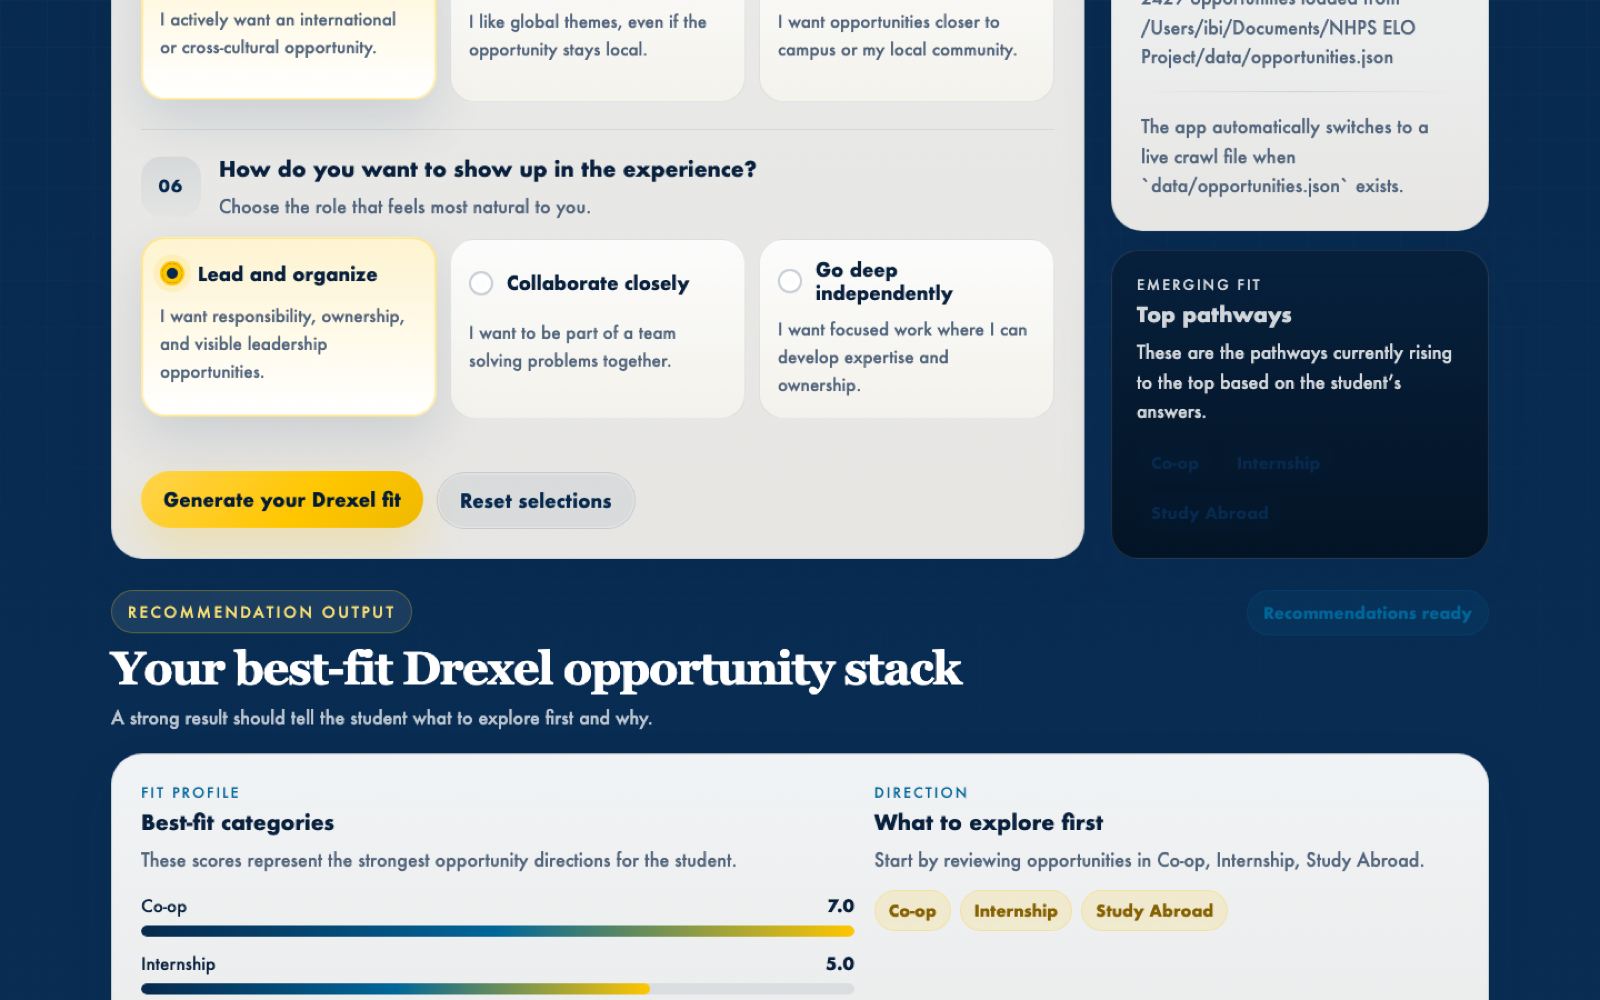
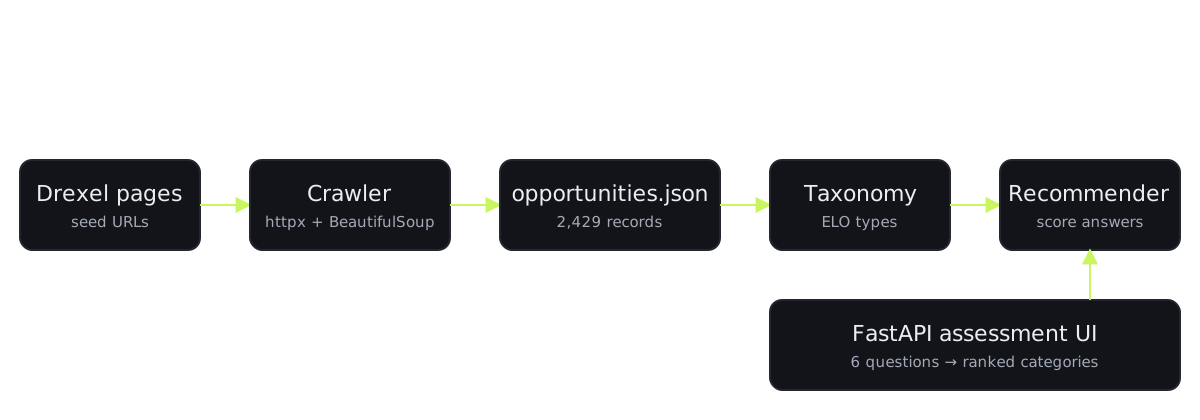
A crawler walks Drexel pages into one inventory, a taxonomy layer sorts records into ELO types, and a scoring engine turns six answers into ranked categories and matching records. Live dataset loaded; runs as a FastAPI app.
Demo
How it works
01
Crawler, taxonomy, and recommender are separate modules with a JSON contract between them.
02
Keyword taxonomy for first-pass classification keeps the pipeline deterministic and free.
03
Assessment answers are scored against category weights, then records are ranked within the top categories.
04
The API reports whether it is serving demo or live data so nobody mistakes synthetic records for real ones.
Stack and code
- Python
- FastAPI
- httpx
- BeautifulSoup
- pytest
recommendations.py— Scoring answers against opportunities.
from typing import Dict, List, Tuple

from elo_recommender.assessment import score_answers
from elo_recommender.models import Opportunity, OpportunityMatch, RecommendationResult
from elo_recommender.taxonomy import category_display_name


def _sorted_scores(category_scores: Dict[str, float]) -> List[Tuple[str, float]]:
    return sorted(category_scores.items(), key=lambda item: item[1], reverse=True)


def _derive_preferences(answers: Dict[str, str]) -> Dict[str, bool]:
    return {
        "prefers_paid": answers.get("compensation_importance") == "essential",
        "prefers_global": answers.get("global_interest") == "yes_high",
        "prefers_service": answers.get("desired_outcome") == "social_impact",
        "prefers_research": answers.get("experience_style") == "discovery_lab",
    }


def _score_opportunity(
    opportunity: Opportunity,
    category_scores: Dict[str, float],
    preferences: Dict[str, bool],
) -> OpportunityMatch:
    score = 0.0
    reasons = []

    matched_categories = []
    for category_id in opportunity.categories:
        category_score = category_scores.get(category_id, 0.0)
        if category_score > 0:
            score += category_score
            matched_categories.append(category_id)

    if matched_categories:
        readable = ", ".join(category_display_name(category_id) for category_id in matched_categories)
        reasons.append("Matches your strongest category fit: {0}.".format(readable))

    if preferences["prefers_paid"] and opportunity.paid:
        score += 1.5
        reasons.append("This opportunity aligns with your need for paid experience.")

    if preferences["prefers_global"] and opportunity.international:
        score += 1.5
        reasons.append("This opportunity supports your interest in global learning.")

    if preferences["prefers_service"] and "community_service" in opportunity.categories:
        score += 1.0
        reasons.append("This opportunity fits your goal of community impact.")

    if preferences["prefers_research"] and "research" in opportunity.categories:
        score += 1.0
        reasons.append("This opportunity supports a project or inquiry-driven learning style.")

    return OpportunityMatch(opportunity=opportunity, score=score, reasons=reasons)


def _build_guidance(category_scores: Dict[str, float], matches: List[OpportunityMatch]) -> List[str]:
    sorted_categories = _sorted_scores(category_scores)
    if not sorted_categories:
        return ["Complete all assessment questions to generate recommendations."]

    top_labels = [category_display_name(category_id) for category_id, _ in sorted_categories[:3]]
    guidance = [
        "Start by reviewing opportunities in {0}.".format(", ".join(top_labels)),
    ]

    if not matches:
        guidance.append(
            "No matching records are in the current dataset yet. Run the crawler or load a reviewed opportunity file."
        )

    return guidance


def recommend_opportunities(answers: Dict[str, str], opportunities: List[Opportunity], limit: int = 6) -> RecommendationResult:
    category_scores = score_answers(answers)
    preferences = _derive_preferences(answers)

    scored_matches = []
    for opportunity in opportunities:
        match = _score_opportunity(opportunity, category_scores, preferences)
        if match.score > 0:
            scored_matches.append(match)

    scored_matches.sort(key=lambda match: match.score, reverse=True)
    top_matches = scored_matches[:limit]
    guidance = _build_guidance(category_scores, top_matches)

    return RecommendationResult(
        category_scores=dict(_sorted_scores(category_scores)),
        matches=top_matches,
        guidance=guidance,
    )
~/Documents/NHPS ELO Project/src/elo_recommender/recommendations.py
taxonomy.py— ELO type taxonomy.
from typing import Dict, List, Tuple


CATEGORY_DEFINITIONS = {
    "research": {
        "display_name": "Research",
        "description": "Faculty-guided inquiry, labs, design studios, and project-based investigation.",
        "keywords": [
            "research",
            "lab",
            "laboratory",
            "faculty mentor",
            "scholar",
            "investigation",
            "project",
            "analysis",
            "thesis",
        ],
    },
    "co_op": {
        "display_name": "Co-op",
        "description": "Structured professional placements tied to workplace experience.",
        "keywords": [
            "co-op",
            "coop",
            "co op",
            "employer",
            "placement",
            "professional practice",
            "career",
            "work experience",
            "full-time",
        ],
    },
    "study_abroad": {
        "display_name": "Study Abroad",
        "description": "International learning, exchange programs, and cross-cultural immersion.",
        "keywords": [
            "study abroad",
            "international",
            "exchange",
            "global",
            "travel",
            "immersion",
            "country",
            "cross-cultural",
        ],
    },
    "community_service": {
        "display_name": "Community Service",
        "description": "Community-based learning, civic engagement, service, and local impact work.",
        "keywords": [
            "community",
            "service",
            "civic",
            "engagement",
            "volunteer",
            "outreach",
            "partnership",
            "public service",
            "impact",
        ],
    },
    "internship": {
        "display_name": "Internship",
        "description": "Shorter-form professional experiences focused on skill building.",
        "keywords": [
            "internship",
            "intern",
            "summer program",
~/Documents/NHPS ELO Project/src/elo_recommender/taxonomy.py
scraper.py— The Drexel crawler.
import argparse
import re
import time
from collections import deque
from dataclasses import dataclass, field
from datetime import datetime
from typing import Dict, Iterable, List, Optional, Set, Tuple
from urllib.parse import urljoin, urlparse, urlunparse
from urllib.robotparser import RobotFileParser

from elo_recommender.models import Opportunity
from elo_recommender.storage import DEFAULT_LIVE_DATA_PATH, save_opportunities
from elo_recommender.taxonomy import categorize_text, looks_like_opportunity, ranked_categories


USER_AGENT = "NHPS-ELO-Recommender/0.1"


@dataclass
class CrawlConfig:
    seed_urls: List[str] = field(default_factory=lambda: ["https://drexel.edu/"])
    allowed_domains: List[str] = field(default_factory=lambda: ["drexel.edu"])
    max_pages: int = 150
    max_depth: int = 3
    delay_seconds: float = 0.25
    timeout_seconds: float = 15.0
    output_path: str = str(DEFAULT_LIVE_DATA_PATH)


def normalize_url(url: str) -> str:
    parsed = urlparse(url)
    cleaned = parsed._replace(fragment="", query=parsed.query)
    normalized = urlunparse(cleaned)
    return normalized.rstrip("/")


def is_allowed_domain(url: str, allowed_domains: Iterable[str]) -> bool:
    hostname = (urlparse(url).hostname or "").lower()
    return any(hostname == domain or hostname.endswith("." + domain) for domain in allowed_domains)


def build_robot_parser(url: str) -> RobotFileParser:
    parsed = urlparse(url)
    robots_url = "{0}://{1}/robots.txt".format(parsed.scheme, parsed.netloc)
    parser = RobotFileParser()
    parser.set_url(robots_url)
    try:
        parser.read()
    except Exception:
        return parser
    return parser


def extract_text_block(raw_text: str, max_length: int = 280) -> str:
    cleaned = re.sub(r"\s+", " ", raw_text or "").strip()
    return cleaned[:max_length]


def infer_booleans(text: str) -> Tuple[Optional[bool], Optional[bool]]:
    lowered = (text or "").lower()
    paid = None
    international = None

    if any(keyword in lowered for keyword in ["paid", "stipend", "salary", "compensation"]):
        paid = True
    if any(keyword in lowered for keyword in ["international", "study abroad", "global", "exchange"]):
        international = True

    return paid, international
~/Documents/NHPS ELO Project/src/elo_recommender/scraper.py